superfluid documentation
One serving daemon for local LLM inference — across runtimes and machines.
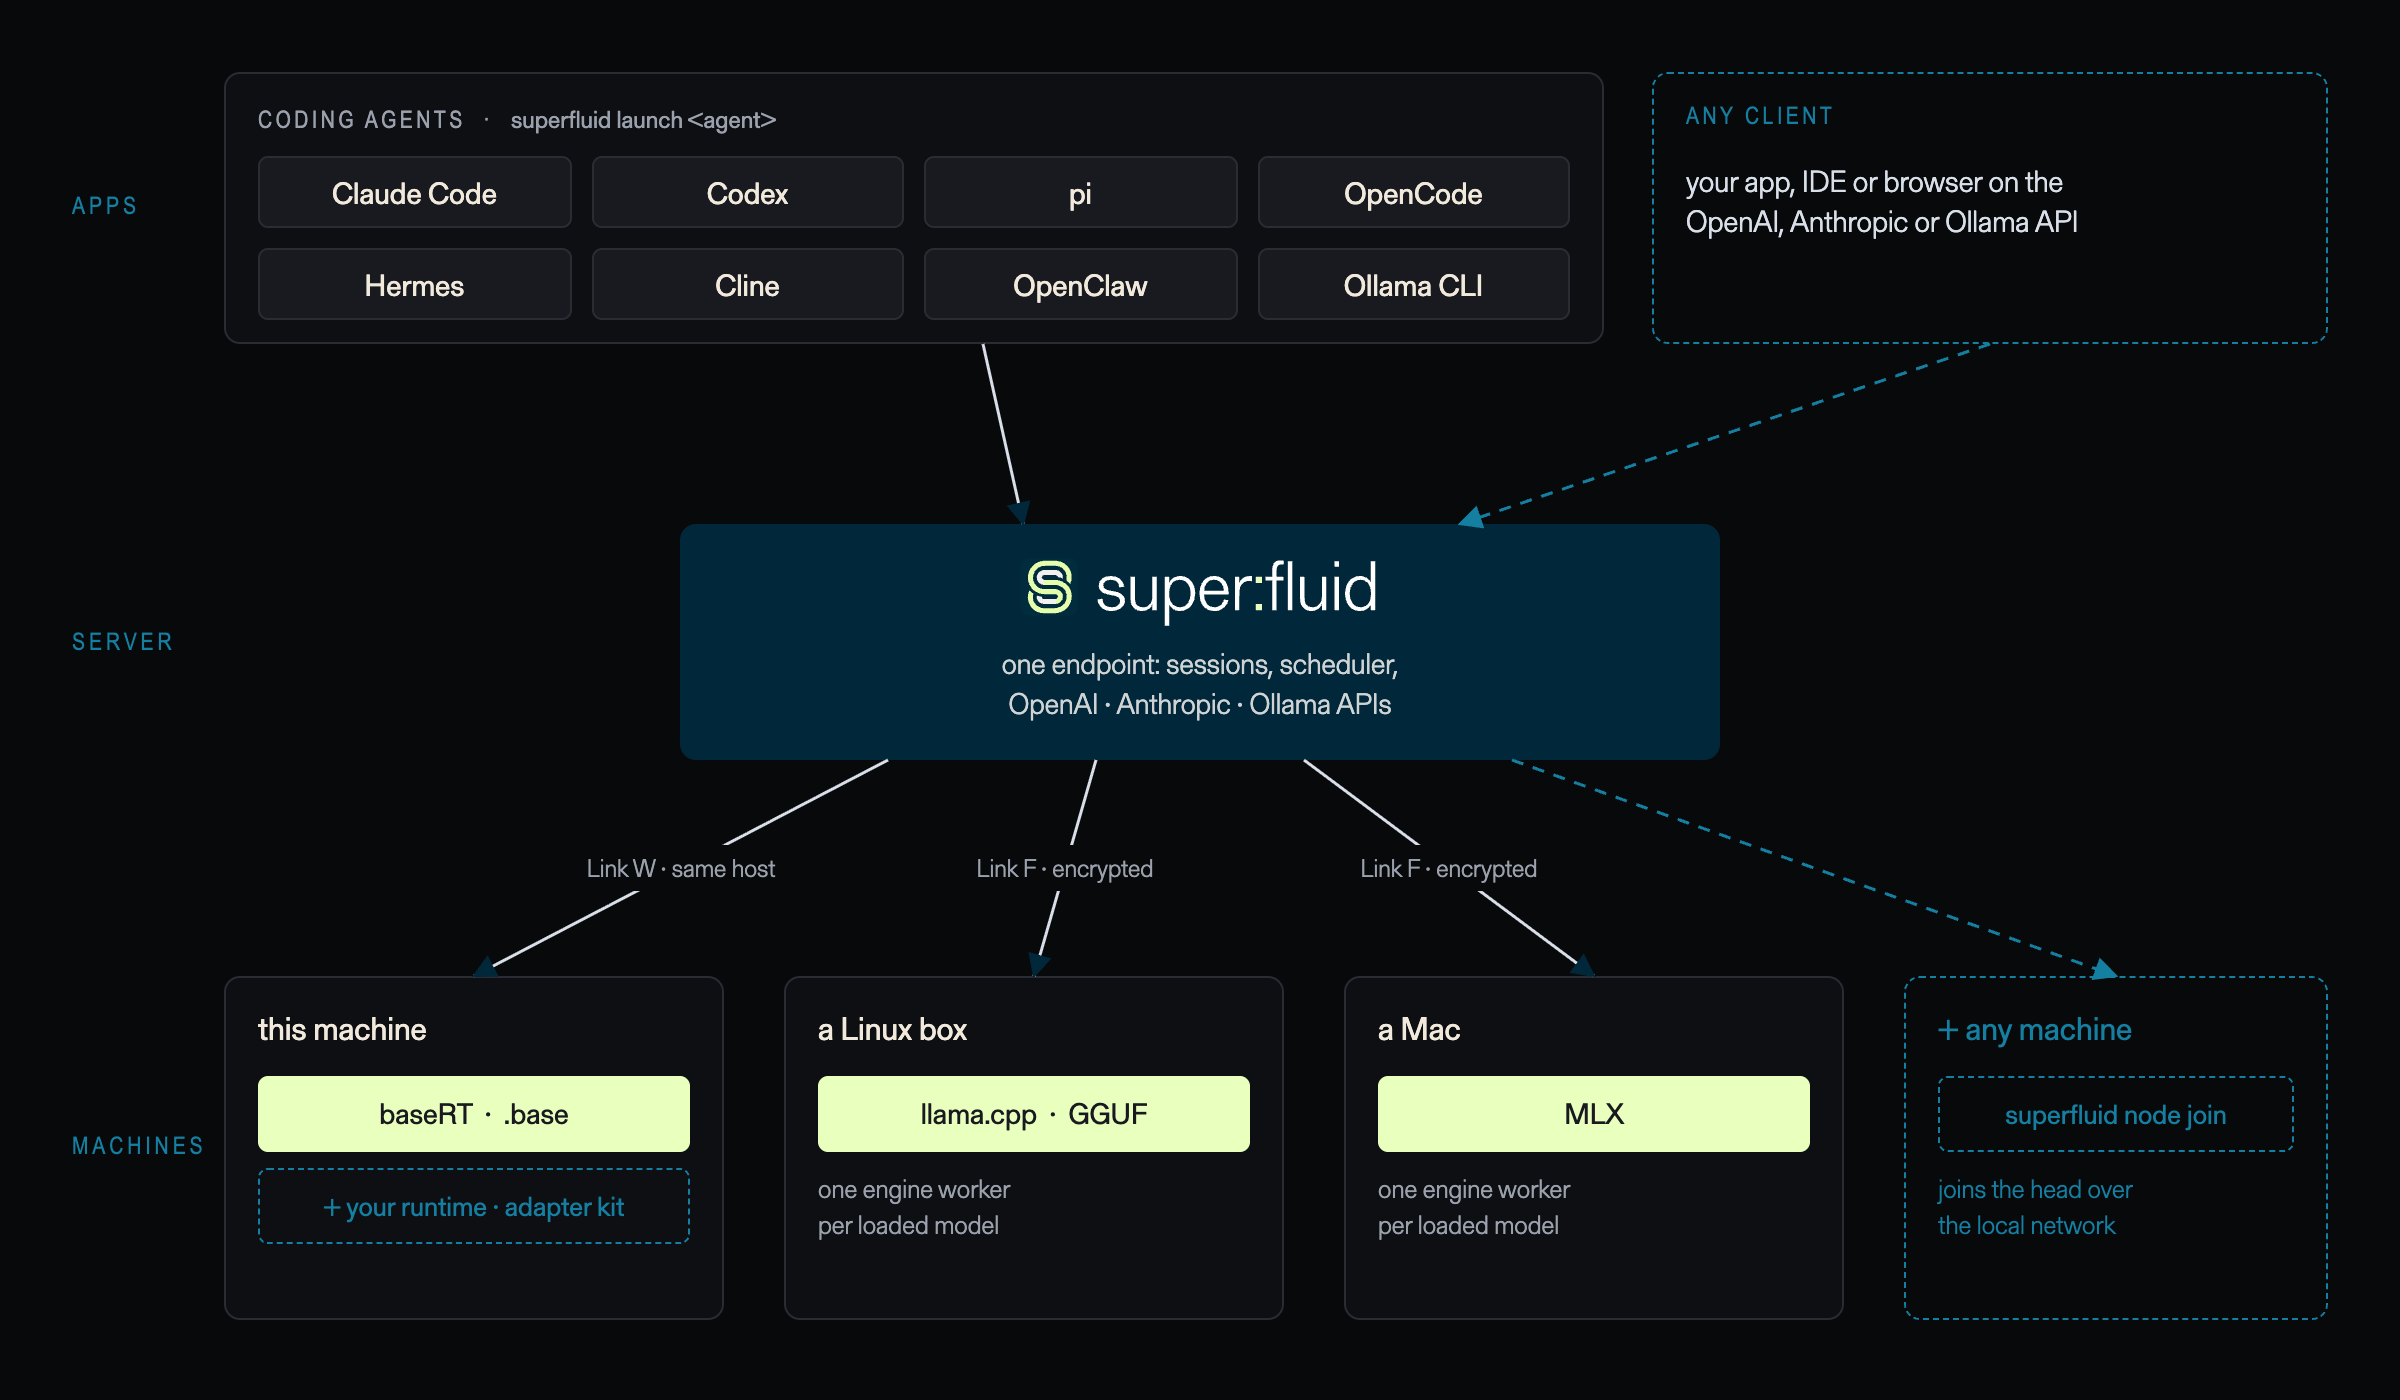
superfluid is a serving daemon for local LLM inference. It puts one scheduler, one durable session log and one set of APIs (OpenAI, Anthropic, Ollama) in front of several inference runtimes: llama.cpp for GGUF files, MLX for MLX directories, and the baseRT engine for .base bundles.
Getting started
Serving
- OpenAI-compatible server
- OpenAI Responses API
- Anthropic Messages API
- Ollama-compatible API
- Session API
- Command-line reference
- Configuration
- Serving multiple models
- Distributed serving (fleet mode)
Integrations
Models
Features
- Tool calling
- Chat templates and reasoning
- Structured outputs
- Sampling
- Speculative decoding
- Vision and audio
- Sessions and prefix caching
- Scheduling and QoS